Instrument theme
Research briefing · 1–19 September 2026

September AI.
Useful decisions.

This month’s useful AI changes span models and the systems around them: visual reasoning, longer agent tasks, managed execution and handoffs across business platforms. Here is what we would evaluate for customers, and the evidence a pilot should produce.

The Little Builder examining model, connector and tool modules at an engineering workbench
Find your next useful AI pilot

Research checked 19 September 2026 · Month to date · Primary sources

OUR PRIORITY

Start with the bottleneck you already have.

For high-volume document work, evaluate DeepSeek V4.1-Flash. For difficult coding and extended investigations, test Claude Fable 5.1. If the model already performs well but the application struggles to keep a task running, look at managed agent runtimes.

These are QQuantum.ai’s evaluation priorities, based on the releases below. They are not claims of completed customer deployments or guaranteed savings. A model release, a beta service and a planned platform integration deserve different levels of commitment.

The useful first question is where work currently stalls: reading evidence, solving a difficult step, resuming a task, or handing it to another system. That answer determines which development deserves attention. Replacing every part of a working application at once makes the benefit harder to measure.

WHAT CHANGED THIS MONTH

Release sources: Anthropic · Genesys · DeepSeek · OpenAI API changelog. Detailed pages retain qualifications beside the relevant claims.

ALSO WORTH YOUR ATTENTION

Voice that can delegate the hard step.

OpenAI’s September changelog also lists GPT-Live 1 as generally available, separating a continuing voice conversation from backend reasoning and tool work. We have added it to the existing voice AI guide, including the published billing distinction. Official release record.

For customers, the opportunity is a support or scheduling conversation that stays responsive while a system checks facts. The pilot should test corrections, interruptions, unsuccessful lookups and transfer to a person. A natural-sounding conversation is only useful if the underlying action is accurate.

CHOOSE A PILOT
Candidate to evaluate Evidence to collect
Document processing is costly DeepSeek V4.1-Flash Accepted fields, review effort and total cost
Difficult coding tasks stall Claude Fable 5.1 Verified fixes, regressions and reviewer time
Agents lose task continuity Managed agent runtime Completion, recovery and complete job cost
Cases get lost between platforms A2A handoff design Resolution, duplicate actions and clear ownership
Calls pause during tool work Delegated voice architecture Interruptions, correct actions and transfers

QQuantum.ai’s proposed pilot criteria. This is a decision matrix, not a benchmark ranking.

HOW THIS FITS WITH JEV

Choose the model. Then finish the work.

Our Jev model-router project addresses which eligible model should receive a request. A managed runtime addresses how work continues, while interoperability addresses where responsibility moves next. These are different parts of an application and can be evaluated independently.

For example, a proposed document assistant could use a permitted visual model to interpret a report, a stronger reasoning model for an unresolved question, and a fast decision layer to select the next route. The application checks permissions before each call and verifies the final evidence. This is an architecture proposal, not a measured performance result.

Start with one stable baseline and a representative set of requests. Change one part, record the effect, and keep a fallback. Count the routing call, every downstream model, retries, tools and human review. Lower headline token prices are useful only when the total cost of an accepted answer improves.

HOW TO READ THE EVIDENCE

Availability and benchmarks need their context.

Research covers announcements available through 19 September 2026, not the whole future month. We prioritised primary release notes and technical documentation, then translated them into proposed customer applications. This is a selective engineering briefing, not an exhaustive news feed.

Provider benchmarks are labelled as such. We do not combine different benchmark versions into one league table or infer live customer savings from token prices. When release notes conflict, the current service documentation governs the integration advice: DeepSeek’s current API notice keeps V4 Pro available, despite the earlier phaseout plan.

QUESTIONS
QUESTIONS — 3

Choose the one that addresses an existing bottleneck with a result you can verify. A short replay evaluation or read-only pilot is usually more informative than replacing a working stack.

No. The briefing covers model releases, an agent runtime, voice capabilities and cross-platform integration. They solve different parts of an enterprise workflow.

The published charts are attributed provider data. Proposed use cases and pilot criteria are our engineering recommendations; we do not present them as completed customer results.

Keep reading

Make the next release
useful to your business.

Tell us where your current workflow is slow, expensive or unreliable. We will help choose a technology and define the evidence needed to adopt it.

CASE STUDIES

Shipped work.
Go and check it.

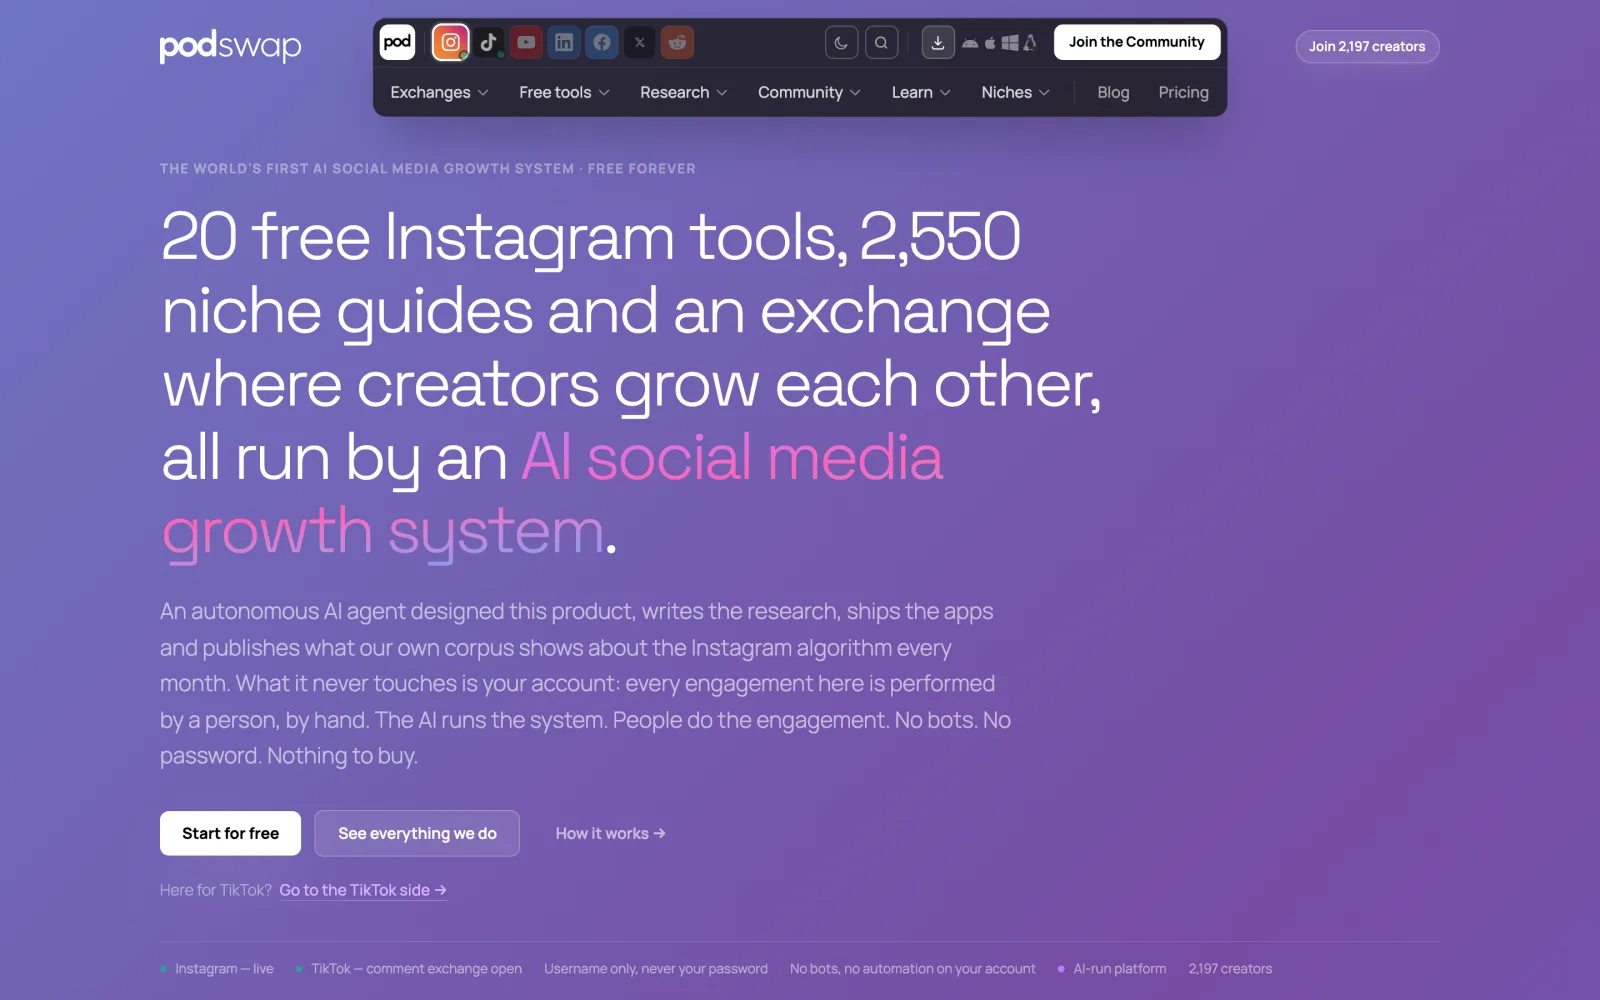
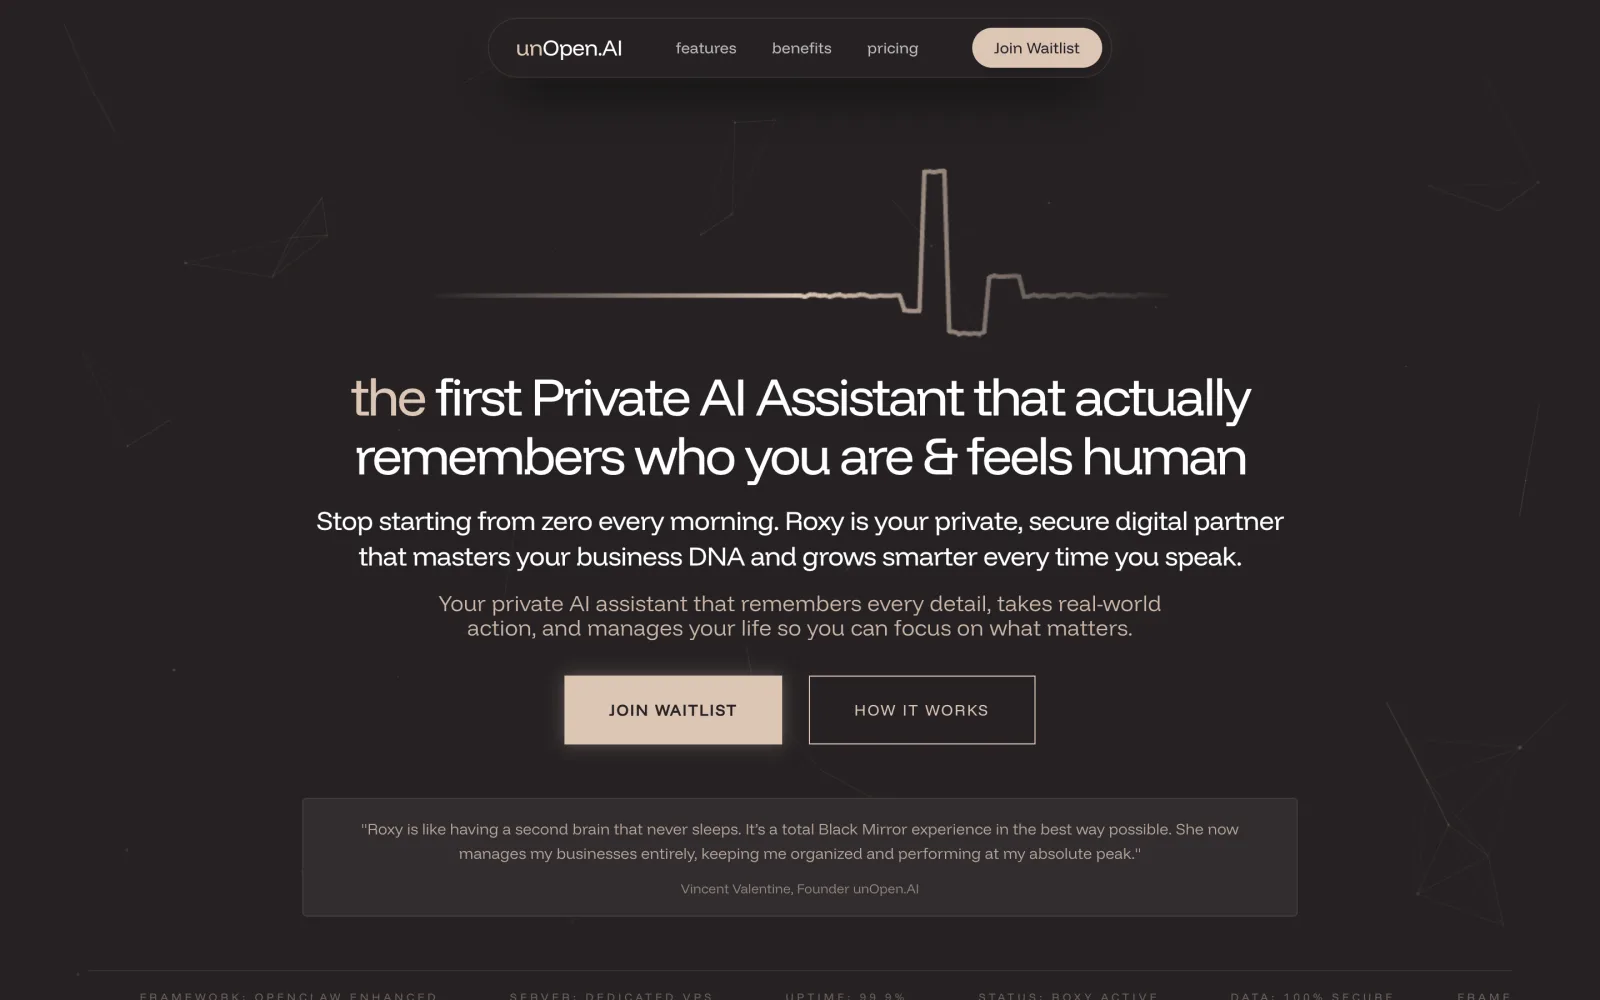
The work we can name, with the live site, our scope and the boundary made explicit. Select a project to see the evidence; each is a full case study, not a logo or a claim.

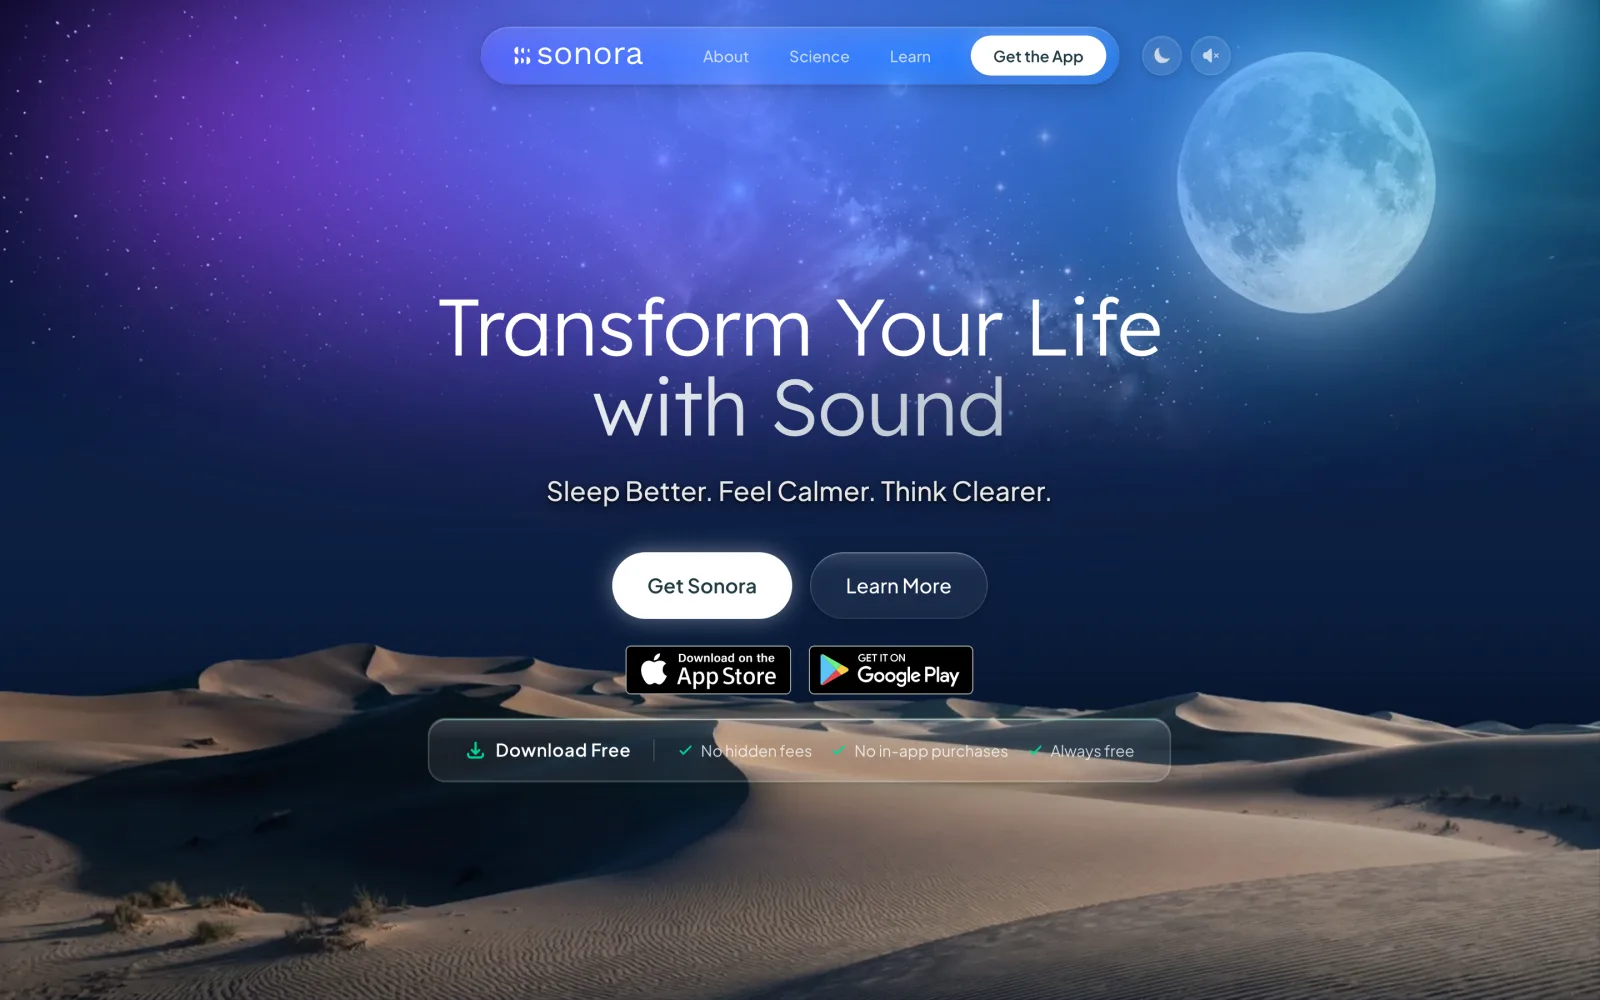
sonora.com
The Sonora homepage on desktop: a full-bleed dune landscape behind the headline “Transform Your Life with Sound”, with App Store and Google Play download buttons.
sonora.com — homepage, 1440×900 sonora.com →
Live Consumer wellness · Mobile + web

Sonora

Cognitive AI Ltd · 2026

A free sound-wellness app, described by its publisher as AI sound therapy that reads a short vocal sample at the start of a session and generates a soundscape for that moment. We designed and built the website and its backend, produced assets for the iOS and Android apps, and supported the application prototype.
Read the case study →

See every published project →

WHO WE HAVE BUILT FOR

Twenty-one years of applications, platforms and campaigns for names you know.

See all of our work →