Bottle theme
Infrastructure

Hybrid model routing.
Local by default.

The all-or-nothing framing of self-hosting is what makes it look like a bad trade. Most mature deployments run a local model for the bulk of requests and escalate a minority — and the interesting engineering is entirely in the gate that decides.

Maker routing work between suitable AI models
THE SHAPE OF A REAL WORKLOAD

Request difficulty in a production system is not normally distributed; it has a long thin tail. Most requests are routine — a classification, a lookup, a summary of a short document, a rewrite. A small proportion are genuinely hard, and a smaller proportion still are hard in ways that need the best available model.

Sending the whole distribution to a frontier API means paying tail prices for the body. Sending it all to a local model means the tail fails, visibly, and users generalise from those failures to the whole system. Routing lets each part go where it belongs, and the cost curve that results looks nothing like either extreme.

The same logic applies to sensitivity, and this is the axis that matters more for a regulated client. Some requests touch material that must not leave the building; most do not. A gate that routes on sensitivity as well as difficulty means the confidential subset is structurally incapable of escalating, while everything else keeps access to the best model available.

For requests eligible for a hosted decision service, our Jev model-router design explores fast task assessment and verification before escalation. Jev itself must pass the same data-handling constraints as any other external provider.
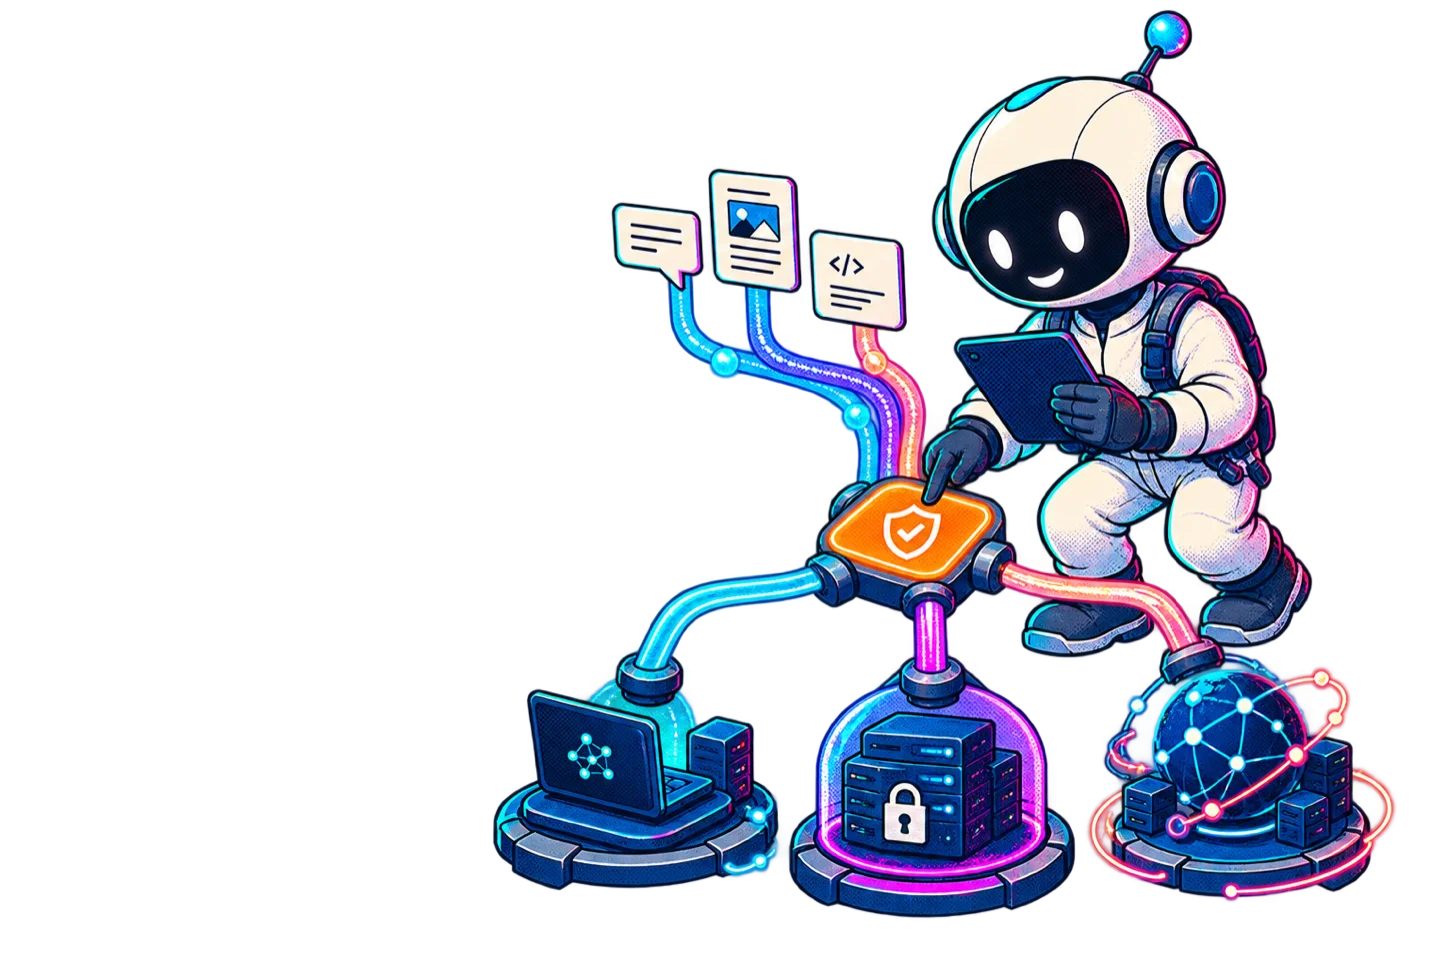

HOW THE GATE WORKS
ROUTING PATH
  1. Request
    from your application
  2. Classify
    sensitivity + difficulty
  3. Local model
    handles the majority
  4. Confidence check
    did it actually answer?
  5. Response
    with route recorded
  6. Frontier escalation
    non-sensitive only, redacted
Solid: the local path, which most requests never leave Dashed: gated escalation for the hard, non-sensitive minority
Sensitivity is evaluated before anything else and is designed as a hard block on escalation, not a weighting in a score.
THE FOUR DESIGN DECISIONS
01

Sensitivity is a hard gate

Not a factor in a score. If a request touches classified material, escalation is unavailable — enforced structurally, ideally by network policy rather than by application logic, because application logic gets refactored by someone who does not know why the branch was there.
02

Escalate on evidence, not guesswork

A pre-classifier guessing difficulty from the prompt is weak. Letting the local model attempt the request and escalating on a measurable signal — refusal, low confidence, failed schema validation, a failed tool call — is far more accurate, at the cost of some latency on the minority path.
03

Redact before you escalate

Non-sensitive is not the same as clean. Names, account numbers and identifiers can usually be replaced with placeholders before a request leaves, and restored in the response. It is unglamorous and it materially narrows what is exposed.
04

Record the route

Every response carries which model answered it. Without that, you cannot debug a quality complaint, cannot attribute cost, and cannot answer an auditor asking whether a specific request ever left the building. It is one field and it is not optional.
WHAT TO MEASURE

Escalation rate, first: the proportion of requests that leave the local model. As a working heuristic, if it climbs above roughly a fifth the local model is probably too small or the gate is too eager, and the economics of the whole arrangement erode quietly.

Then escalation precision, which is the number people skip. Of the requests that escalated, how many did the frontier model actually answer better? If the answer is not most of them, the gate is firing on the wrong signal and you are paying for nothing. This needs a periodic sample scored against both, which is a small standing cost with a large return.

And unnecessary local failures: requests the local model got wrong that did not escalate. These are the expensive ones, because they reach a user as a confidently wrong answer. They are found by sampling, not by monitoring, which is why the evaluation harness has to keep running after launch rather than being a launch gate.

QUESTIONS
QUESTIONS — 4

On the escalated path, yes — you have paid for a local attempt before making a remote call. On the majority path it is faster, because the local model has no network round trip. Whether the average improves depends on your escalation rate, which is the number to watch.

Usually from metadata you already have rather than from the text: which system the document came from, which folder, which user, which classification label. Inferring sensitivity from content with a model is a fallback, not a foundation — it is probabilistic, and this gate should not be.

Yes, and sometimes it should: frontier first, with a local model absorbing repeated or cacheable requests. That suits workloads where quality dominates and volume is moderate. The routing machinery is the same; only the default changes.

It can be. If you have one model, low volume and no sensitivity constraint, route everything to it and revisit when one of those three changes. What we would still build on day one is the recorded-route field, because retrofitting attribution across a live system is far more work than adding it at the start.

Keep reading
30-minute technical call · no deck

Best of both,
deliberately.

We build the gate, instrument it, and show you the escalation rate before you commit to hardware.

CASE STUDIES

Shipped work.
Go and check it.

The work we can name, with the live site, our scope and the boundary made explicit. Select a project to see the evidence; each is a full case study, not a logo or a claim.

sonora.com
The Sonora homepage on desktop: a full-bleed dune landscape behind the headline “Transform Your Life with Sound”, with App Store and Google Play download buttons.
sonora.com — homepage, 1440×900 sonora.com →
Live Consumer wellness · Mobile + web

Sonora

Cognitive AI Ltd · 2026

A free sound-wellness app, described by its publisher as AI sound therapy that reads a short vocal sample at the start of a session and generates a soundscape for that moment. We designed and built the website and its backend, produced assets for the iOS and Android apps, and supported the application prototype.

Read the case study →

See every published project →

WHO WE HAVE BUILT FOR

Twenty-one years of applications, platforms and campaigns for names you know.

See all of our work →





















