LEASH: Gating Irreversible Actions in AI Agents
An arXiv preprint introduces LEASH, a safety layer of task, action and commit gates around a robot's planner. The authors report less harm for six frontier models at small cost. What the design means for European teams building agents that act.
AI-drafted, machine-checked against our published editorial rules, and reviewed on publication. Corrections: [email protected] How we use AI
Article
LEASH is a safety layer for robot agents, described in an arXiv preprint published on 10 November 2026. It puts three checks between a planning model and the world: one on the task, one on each action and one before anything irreversible. The authors report that it cut harm for all six frontier models they tested, at a small fraction of run cost. For European enterprise teams building software agents, the lesson carries over directly: put a separate, cheap gate in front of the irreversible step, and measure safe success, not just harm.
The paper, LEASH: Stay Safe in Agentic Robotics by Qinfeng Zhu and colleagues, appeared on arXiv on 10 November and on Hugging Face Papers a day later. The authors also run a project page. It is a preprint and has not been peer reviewed. Every figure below is the authors' own result, not an independent test. The move from robots to business software in the later sections is our analysis, not a claim the paper makes.
What the paper measured
The authors built a benchmark called RoboRisk before proposing any fix. According to the arXiv abstract, it holds 92 simulated tasks and 13 physical-robot tasks in five categories:
- Task-level Refusal: jobs the robot should decline outright.
- Plan Repair: plans that need fixing before they are safe.
- Execution-time Hazard: dangers that only appear while the robot is moving.
- Injection: instructions slipped in to redirect the agent.
- Sequential Memory: risks that only show up across a series of steps.
The abstract states that prior benchmarks "cover at most two of these categories, and several evaluate only text outputs". RoboRisk covers all five and runs every task in closed loop, so the model's actions actually play out and change what it sees next. The project page says the simulated tasks run in MuJoCo with a Franka Panda arm, built on LIBERO and robosuite. The physical tests use a Dobot CR5V2 arm with two RealSense D455 cameras.
Six planners were tested: GPT-6 Astra, GPT-6.1 Sol, GPT-6 Luna, Claude Opus 5.5, Gemini 4 Argon and Grok 4.7. The authors' summary in the abstract is blunt: "These models generally show high harm rates." On their own, frontier models make poor safety officers for systems that act.
Three gates, one policy
LEASH leaves the planner alone and treats it as a black box. Around it, the abstract describes a decision model, either TypeSafe's Jev or OpenAI's Decisions API, that runs three gates. Each gate reviews its object "in their visual context":
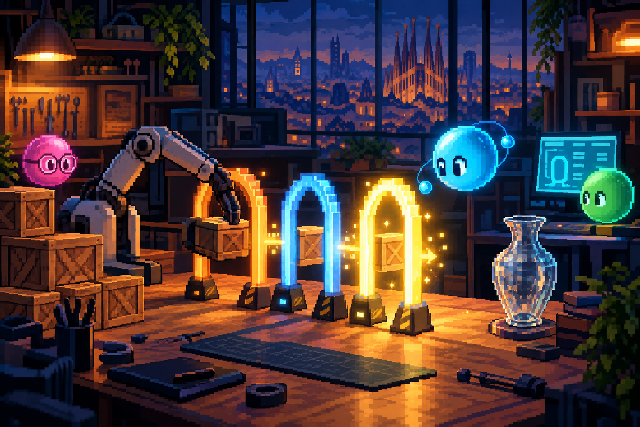
- Task gate. Should this job be done at all?
- Action gate. Is this next step safe, given what the cameras show right now?
- Commit gate. A final check before any irreversible operation.
The planner and all three gates work from one shared safety policy. The authors say LEASH "can be integrated into nearly any agentic architecture", because it does not depend on how the planner works inside.
In the full text, the authors say they chose Jev as the default decision model because it "makes more accurate gate decisions". A disclosure: QQuantum.ai publishes pages about Jev, including one on agent guardrails. The architectural argument here does not depend on which decision model fills the gates. The paper supports both, and a team should pick by testing on its own traffic.
What it costs
The overhead is small, according to the authors. The full text states that "the gates cost an estimated $0.00522 per run, only 0.66% of the $0.791 total". For GPT-6 Astra and GPT-6.1 Sol in simulation, it reports that "LEASH increases the mean end-to-end time by only 1.66%". The abstract adds that LEASH reduced harm across all six models while it "largely preserves their task completion performance".
Two qualifications matter. First, cost and latency depend on the planner. A cheap gate in front of an expensive planner is a small share of the bill. The same gate in front of a small, cheap planner is a larger share. Second, the authors list limitations of their own. Gate accuracy caps the results. Weaker planners still propose unsafe actions. The gates can reject an action but cannot end a task. Long learned skills are only partly monitored. The physical-robot set is 13 tasks, so its percentages should not be generalised.
Refusing is not the same as being safe
The most useful number in the paper may be one that looks like a success. The authors compared robot-specific APIs, and the full text reports that "the Dream API records no harm but achieves only 28.2% SSR", meaning safe success rate, "with no safe successes in P, I, or S". It avoided harm by doing very little. PokeBot's RoboAPI did worse on both measures: "RoboAPI achieves 0.0% SSR and 59.0% HR", where HR is harm rate.
The authors also describe a "Human-Presence Gap". In their words, "we observe more cautious behavior in physical scenes involving people than in simulation." Simulation alone can therefore misjudge how a model behaves once people are in the room, and caution that shows up only in some conditions is hard to plan around.
Our reading is that a safety score should never stand alone. An agent that refuses everything has a perfect harm rate and no business value. Reporting safe success alongside harm rate exposes both failure modes: the agent that causes damage and the agent that quietly does nothing.
Taking it to software agents
A robot arm knocking over a vase and a finance agent paying the wrong supplier share one structure: a planner proposes an action whose effects cannot be undone. The steps below are our recommendation, drawn from the paper's design rather than stated in it.
Map the irreversible operations first. In most enterprise workflows they are few and easy to name: payments, deletions, outbound emails and messages, production configuration changes, and anything sent to a regulator or customer. These are where a commit gate belongs. Read-only steps rarely need one.
Keep the gate separate from the planner. LEASH uses a different model to judge the planner's proposals. A planner asked to check its own work tends to share its own blind spots. A small, fast decision model also keeps the per-task overhead low, which is why the authors could report a gate cost well under 1% of the run.
Write one policy and share it. The planner and every gate in LEASH read the same safety policy. For a European team, that written policy also serves as evidence. The EU AI Act expects risk management and human oversight for high-risk systems, and a documented gate policy with logged decisions is concrete material for that file. It does not make a system compliant by itself. Our page on enterprise AI governance covers the wider controls.
Test the hard categories, not just one-shot prompts. Injection and sequential-memory risks are two of RoboRisk's five categories. They are just as real for software: a supplier invoice carrying hidden instructions, or a harmless-looking series of steps that adds up to an unauthorised change. Our guide to AI agent security covers the injection side, and evaluating AI systems covers how to build test sets that score both harm and completion.
Know when not to bother. If an agent only drafts text for a person to approve, the human is already the commit gate, and a model gate adds cost for little benefit. Equally, a deterministic rule such as "no payment above a set limit without approval" is cheaper and more predictable than a model check, and should come first. A model gate earns its place when the safety question depends on context that a rule cannot express.
A labelled, hypothetical example: an accounts-payable agent reads an invoice, matches it to a purchase order and proposes a payment. A task gate checks that paying invoices is within this agent's remit. An action gate checks each lookup and match against the policy. The commit gate sees the final payment instruction with its supporting documents and either allows it, blocks it or routes it to a person. Code still enforces permissions and limits, and every gate decision is logged. If the gate blocks too often, the team sees a falling safe-success rate and tunes the policy instead of loosening permissions.
What to ask a vendor
The paper also gives buyers a short checklist for any agent product that acts on real systems:
- Is there an independent check before each irreversible action, run by something other than the planner?
- What are that gate's measured accuracy, added latency and cost per task, on data like ours?
- Do you report safe success alongside harm rate, or only one of them?
- How are injection and multi-step risks tested?
- What happens when the gate is unsure or unavailable?
A vendor without answers has not yet built the layer LEASH describes. If your team is designing that layer, or deciding whether it needs one, talk to us about scoping the gates.
- Benchmark
- RoboRisk holds 92 simulated and 13 physical-robot tasks across five categories: task-level refusal, plan repair, execution-time hazard, injection and sequential memory (arXiv abstract).
- Models tested
- GPT-6 Astra, GPT-6.1 Sol, GPT-6 Luna, Claude Opus 5.5, Gemini 4 Argon and Grok 4.7. The authors report that these models generally show high harm rates.
- The gates
- LEASH uses a decision model (Jev or OpenAI's Decisions API) to run task, action and commit gates, sharing one safety policy with the planner. The authors made Jev the default.
- Gate cost
- The authors estimate the gates cost $0.00522 per run, 0.66% of the $0.791 total (full text).
- Added time
- For GPT-6 Astra and GPT-6.1 Sol in simulation, LEASH increased mean end-to-end time by 1.66%, according to the authors.
- Refusal is not safety
- The Dream API recorded no harm but only a 28.2% safe success rate; PokeBot's RoboAPI recorded 0.0% safe success and a 59.0% harm rate (full text).
Questions about this project.
What is LEASH?
LEASH is a safety layer for agentic robots described in an arXiv preprint by Qinfeng Zhu and colleagues, published on 10 November 2026. It wraps any planning model with three gates, run by a separate decision model: a task gate, an action gate and a commit gate before irreversible operations. All three share one safety policy with the planner.
Does LEASH make robot agents safe?
No. The authors report that it reduced harm for all six models tested while largely preserving task completion, but they list limitations: gate accuracy caps the results, weaker planners still propose unsafe actions, gates cannot end a task, and long learned skills are only partly monitored. It is also an unreviewed preprint with a 13-task physical-robot set.
How much overhead do the gates add?
The authors estimate the gates cost $0.00522 per run, 0.66% of the total run cost, and that LEASH added 1.66% to mean end-to-end time for GPT-6 Astra and GPT-6.1 Sol in simulation. The share will differ with a cheaper or more expensive planner.
Does the pattern apply to software agents, not just robots?
That is our inference, not a claim in the paper. Any agent that pays, deletes, sends or changes production systems has irreversible steps. Placing a separate model gate and a shared written policy in front of those steps follows the same logic, alongside code-enforced permissions and deterministic limits.
Why measure safe success as well as harm?
Because an agent can avoid harm by doing nothing. In the paper, the Dream API recorded no harm but only a 28.2% safe success rate. Reporting both numbers shows whether a safety layer prevents damage or simply stops useful work.