OpenAI GPT-6 Astra: Benchmarks, Pricing and Enterprise Agents
OpenAI GPT-6 Astra brings stronger reasoning, coding and computer-use capabilities to agent workloads. Its enterprise value depends on scoped access, verified actions and cost-aware orchestration around the model.
AI-drafted, machine-checked against our published editorial rules, and reviewed on publication. Corrections: [email protected] How we use AI
OpenAI GPT-6 Astra is a frontier model for reasoning, coding and computer use. For an enterprise, its value depends on connecting those capabilities to a defined workflow with scoped permissions, verified outputs and cost controls. The model can handle more of a task, but it does not replace the system that decides what it may access or commit.
What GPT-6 Astra adds to agent workloads
OpenAI positions Astra for complex, end-to-end work across research, coding, documents and computer use. Its API documentation lists a 1,050,000-token context window, up to 128,000 output tokens, and support for tools including computer use, hosted shell and code interpreter. OpenAI's model documentation is the authoritative source for those limits and supported tools.
That makes Astra relevant to workflows where an agent must inspect a set of records, decide what requires attention, operate a business system and explain the outcome. It does not turn every task into a good candidate for browser or terminal automation. Where a stable API and deterministic rule can complete a step, they are usually easier to audit and cheaper to run.
Context capacity is also not persistent memory. It describes the information available during a request. A production application still needs to decide what state to retain, who may access it, how evidence is retrieved, and how a task resumes after an interruption. Those decisions belong in the orchestration layer, not in a prompt alone.
What the reported evaluations establish
OpenAI reports 72.6% on OSWorld 2.0, 41.4% on AutomationBench and 57.9% on Terminal-Bench 4.0. Its comparison table reports 37.3% for GPT-5.6 Sol on Terminal-Bench 4.0. The same table lists 96.0% on GPQA Diamond, 97.6% on FrontierMath Tier 4 (v2) and 99.9% on ARC-AGI-3. OpenAI's launch report and detailed tables provide the benchmark versions and comparison conditions.
| Evaluation | Astra result reported by OpenAI | Comparison or qualification |
|---|---|---|
| OSWorld 2.0 | 72.6% | Computer and browser task benchmark |
| AutomationBench | 41.4% | Automation task benchmark |
| Terminal-Bench 4.0 | 57.9% | OpenAI's table lists GPT-5.6 Sol at 37.3% |
| GPQA Diamond | 96.0% | Scientific reasoning evaluation |
| FrontierMath Tier 4 (v2) | 97.6% | Mathematical reasoning evaluation |
| ARC-AGI-3 | 99.9% | Abstract reasoning evaluation |
The figures show progress on defined tests. They do not establish that an agent will be reliable on an organisation's own permissions, data quality, applications or exception handling. A benchmark for terminal tasks is not a forecast for a finance workflow, and a computer-use demonstration is not proof that an agent can safely make consequential changes without review.
For a pilot, the useful question is narrower: can the model complete representative work with an acceptable error rate, a clear recovery path and an evidence trail? That is the purpose of application-specific AI evaluations. Measure the cases that matter to the team, including ambiguous inputs and failures, rather than treating a public benchmark as an acceptance test.
Pricing changes the system design
OpenAI lists Standard text prices of $10 per million input tokens and $50 per million output tokens. Cached input is listed at $1 per million tokens and cache writes at $12.50. The API documentation also says that requests above 272,000 input tokens are priced at twice the input and cache rates and 1.5 times the output rate for the full request. Tool calls such as search or computer use have additional charges. OpenAI's pricing details should be checked again when a pilot begins.
For illustration, a request using 100,000 uncached input tokens and 5,000 billed output tokens costs $1.25 in Standard text tokens: $1.00 for input and $0.25 for output. This excludes tool calls, infrastructure, retries, human review and any long-context price step-up. It is a planning example, not a quote or a prediction of a workflow's total cost.
That arithmetic favours hybrid model routing. A system can use rules or smaller models for ordinary extraction and validation, then reserve Astra for the genuinely ambiguous decision. The right route depends on quality, sensitivity, latency and cost, not on a model name alone.
A worked example: invoice reconciliation
Consider an illustrative invoice-reconciliation workflow. A scoped connector retrieves invoices and purchase orders through an API. Deterministic rules match ordinary records using supplier, amount and reference number. Astra receives only ambiguous cases with the relevant evidence, then proposes a match or an escalation reason.
Before any adjustment is posted, the application validates returned record identifiers and totals against the source system. A finance user reviews exceptions above an agreed threshold. The service records the authorised action, source references, resulting status and estimated cost, while keeping secrets and unnecessary document contents out of the log. If a later step fails, the workflow resumes from its checkpoint and checks whether an adjustment already exists before retrying.
Browser operation can help when a legacy system has no usable API. It adds moving-interface risk, so it should be bounded by a dedicated account, a small task scope and a verification step. For an API-only workflow, a browser agent or a micro-VM may add complexity without improving the result.
Why capability needs guardrails
OpenAI says Astra is its first broadly deployed model to reach the Critical cybersecurity capability level under its Preparedness Framework. Its safety overview states that, with suitable tools and access, the model can find previously unknown flaws and develop exploit paths. OpenAI's safety overview also describes strengthened safeguards around deployment.
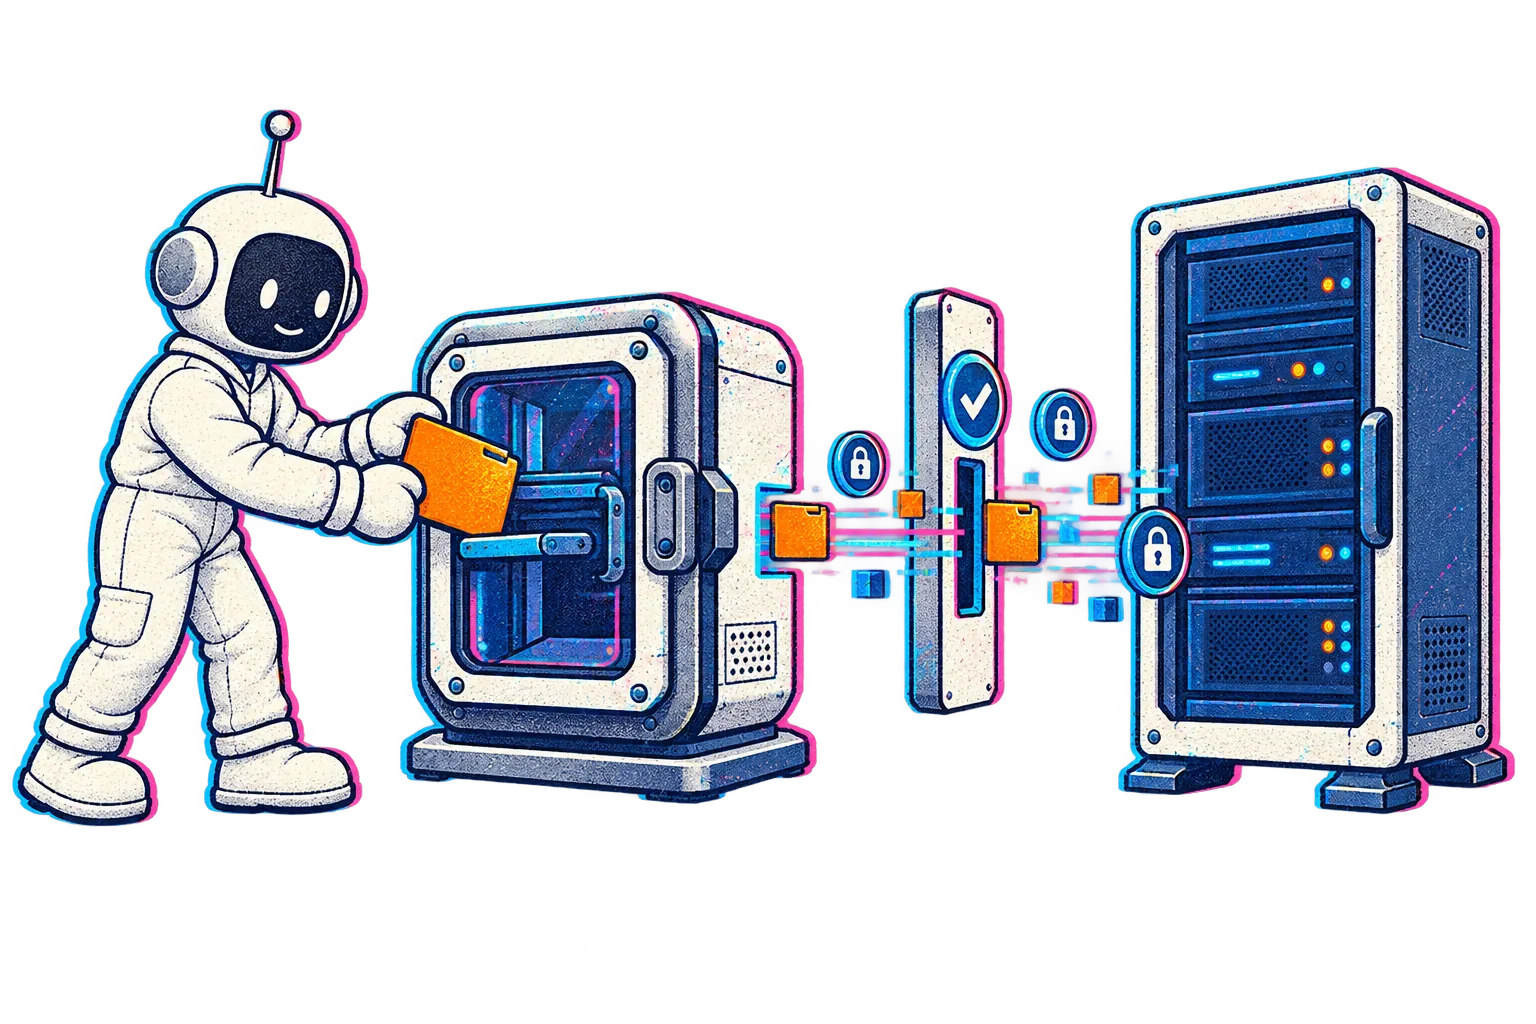
The practical implication is not that every Astra API request is unsafe. It is that authority must be designed deliberately. An enterprise agent needs a narrow identity, limited tool permissions, defined data boundaries, action validation and a trace that can be reviewed when something goes wrong. Security architecture should be proportionate to the workflow: an agent that drafts a summary needs different controls from one that changes supplier records.
Custom orchestration becomes useful when work crosses systems, uses sensitive data, needs approval before a consequential action, or must show why an answer was accepted. It is less valuable when a narrow workflow can be completed with a stable API call and a deterministic check.
The enterprise question
The right starting point is one workflow, not a general licence for autonomous computer use. Define the input, allowed tools, completion criteria, exceptions, approval point and recovery path. Then compare Astra with simpler options on representative cases.
QQuantum.ai designs the surrounding architecture: model selection, retrieval, scoped connectors, evaluation, observability and the controls required for an agent to operate safely in a real business process. If a team is assessing a computer-use workflow, book a technical conversation to map the controls and evidence it would need before a pilot.
Sources
- Computer use
- OpenAI reports 72.6% on OSWorld 2.0, a benchmark for computer and browser task completion.
- Terminal work
- OpenAI reports 57.9% on Terminal-Bench 4.0, compared with 37.3% for GPT-5.6 Sol in its table.
- Context limit
- The API lists a 1,050,000-token context window and up to 128,000 output tokens; application memory remains a separate design choice.
- Standard price
- Standard text pricing is listed as $10 per million input tokens and $50 per million output tokens, before applicable tool charges and long-context pricing.
- Cybersecurity
- OpenAI classifies Astra at the Critical cybersecurity capability level under its Preparedness Framework.
GPT-6 Astra is OpenAI's frontier model for complex reasoning, coding, research, document creation and computer use. It is designed for hard end-to-end tasks, but deployment controls remain the responsibility of the organisation using it.
They establish results on specific evaluation suites under OpenAI's stated conditions. They do not establish reliable performance on every internal system, permission model or changing browser workflow, so a pilot should use representative tasks and measured acceptance criteria.
OpenAI lists Standard text rates of $10 per million input tokens and $50 per million output tokens. Prompts above 272,000 input tokens have higher rates, and tool calls, infrastructure, retries and application work add to the total cost.
No. Context capacity is the amount of information available to a request. Durable memory, retention, access control and recovery after failure need to be designed and operated by the application.
Custom orchestration is useful when a workflow crosses sensitive systems, needs approval before consequential actions, requires evidence-backed outputs or must control cost. A narrow API workflow may need much less infrastructure than a browser or terminal agent.
























